AI agents read documents, follow links, use tools and act on behalf of people. Misleading instructions can enter through any of these interactions. An agent platform needs controls that continue to enforce permissions, check actions and limit exposure when a model is deceived.
Qonstrue applies these guardrails across conversations, sub-agents and blueprints running in the background. All inputs are treated as untrusted, checks run throughout an agent’s work, and all outbound mechanisms are guarded. Customers can review guard decisions through their in-app dashboard.
Our approach aligns these controls with the 2026 OWASP Top 10 for LLM Applications and the OWASP Top 10 for Agentic Applications.
Why OWASP
OWASP’s frameworks provide a shared vocabulary for identifying and addressing risks in AI applications.
The Top 10 for LLM Applications covers risks such as prompt injection, sensitive information disclosure and excessive agency. The Top 10 for Agentic Applications addresses risks associated with systems that plan, use tools, retain context and delegate work.
We use both frameworks to review our controls and explain the risks they help address. The mapping provides a basis for assessment; it does not mean that every attack can be prevented.
Guardrails throughout the agent’s work
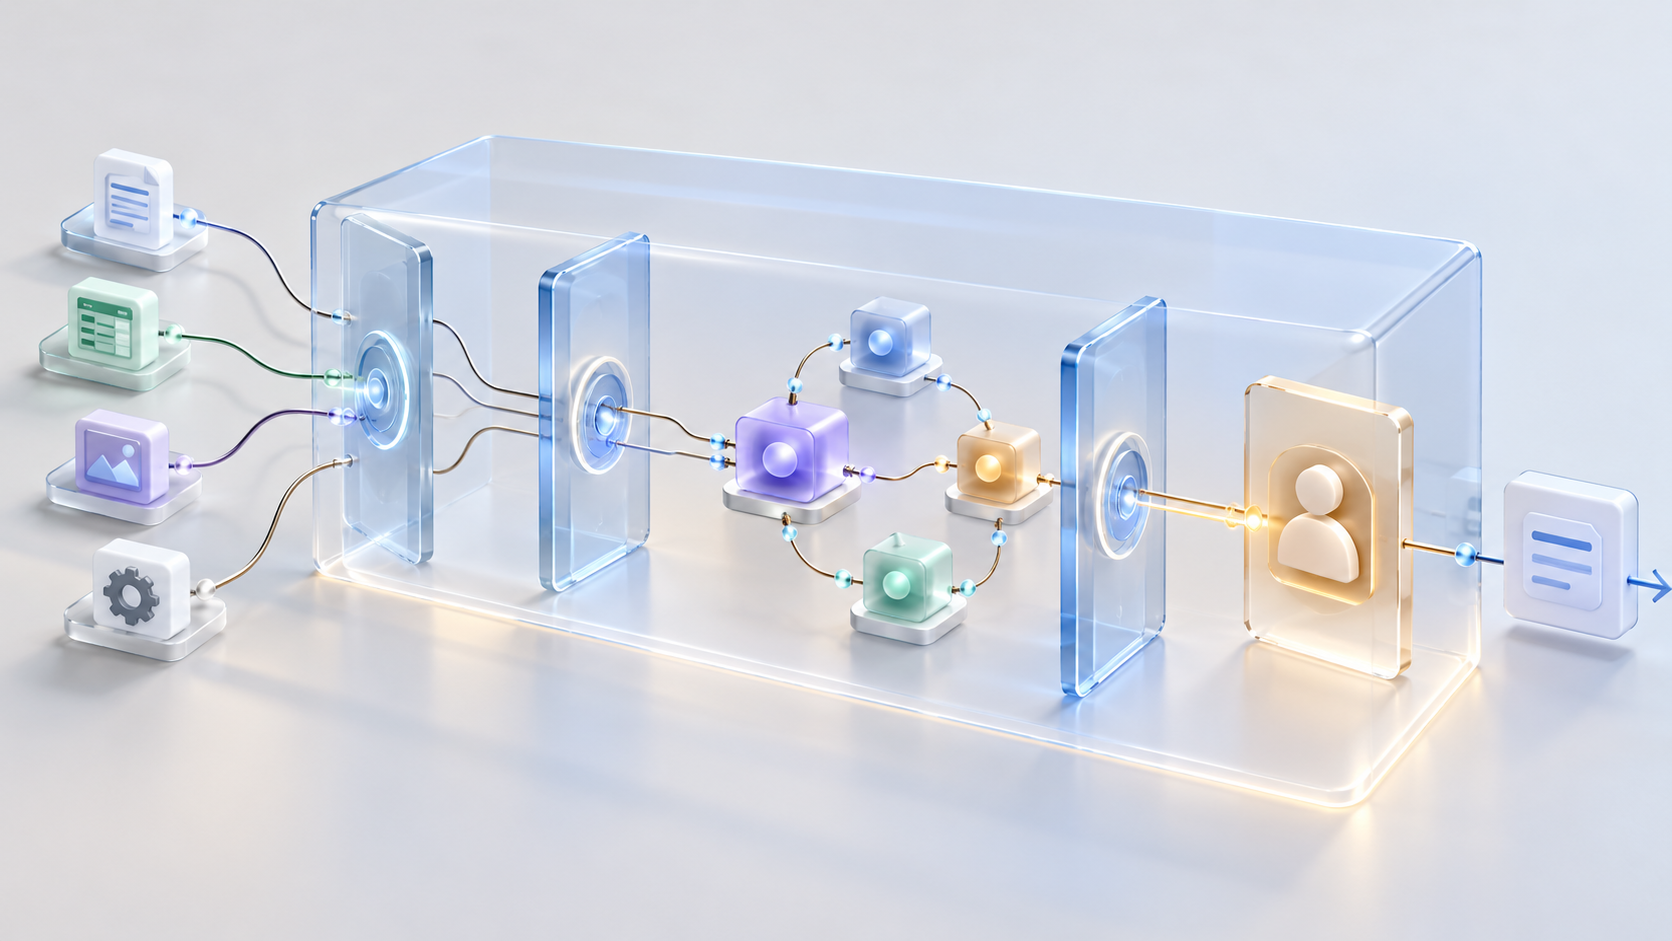
Qonstrue’s controls operate at defined points throughout a run: when input enters the system, before model calls, when tools return results and before information leaves the workspace.
These controls are enforced today across interactive and background work.
All inputs are treated as untrusted
Blueprint instructions, user messages, uploaded documents, linked pages and tool results all pass through checks.
Guards look for attempts to redirect the agent, exposed credentials and sensitive information. Content retains information about its origin, helping distinguish material the agent is examining from instructions governing its operation.
These checks work alongside access controls. Reading a document or receiving a tool result does not grant the agent additional permissions.
Access stays within the workspace’s authorisation boundaries
The environment available to an agent reflects the workspace owner’s authorised access. The model’s interpretation of a request cannot expand those permissions.
Actions proposed by the model remain subject to platform checks before execution. Agent-generated code runs in an isolated environment within those authorisation boundaries.
This separation matters when a model makes the wrong decision: a proposed action must still satisfy the controls governing access and execution.
All outbound mechanisms are guarded
Qonstrue checks information leaving the workspace across outbound mechanisms. Actions that send data outside the workspace pause for customer approval.
Approval requests show what is about to be sent, allowing customers to review the proposed action before it proceeds. These requirements continue to apply when an action follows instructions encountered in a document, linked page or tool result.
An open-source gateway adds another enforcement point
Model requests pass through the open-source AI gateway Qonstrue uses. The gateway checks requests separately from the guards within the agent, adding another enforcement point before requests reach a model provider.
It provides a shared place to apply model-request protections across the platform, alongside the controls governing workspace access, tool use and outbound actions.
Qonstrue is committed to contributing to the gateway’s development and helping grow its capabilities as an open-source project.
Run limits contain excessive execution
Each run has limits on model calls, token use and depth. These limits help contain loops, repeated delegation and excessive consumption.
Restricted retries also help prevent temporary faults from producing unnecessary repeated execution.
Customers can review guard decisions
Guard decisions are recorded for the customer’s organisation, retained for 90 days and available through the in-app dashboard.
This gives customers visibility into when guards intervened and the decisions they made, supporting review and investigation.
Alignment with the OWASP Top 10 for LLM Applications
The following mapping uses the 2026 categories. It identifies controls relevant to each risk; individual safeguards address parts of a risk rather than guaranteeing its elimination.
Alignment with the OWASP Top 10 for Agentic Applications
Agentic workflows introduce additional risks through tool use, persistent context and delegation. The following controls address these interactions.
Maintaining the controls
Agent capabilities and attack methods continue to evolve. We review our guardrails against OWASP guidance and use operational experience to identify where protections need improvement.
Customers can inspect guard decisions in Qonstrue and speak with our team about how these controls apply to their workflows.
Our objective is to keep access boundaries, action checks and customer approvals enforced throughout an agent’s work—including when the model is misled.